
Computer Vision · Image and text
Multimodal AI in the Enterprise: Images, Documents and Text in One System
Many business processes involve more than text: photos of damage, scanned delivery notes, meter readings, labels, forms. Multimodal models understand image and text together and can take on such tasks without large training datasets. This overview shows where that holds up today and where it does not.
 Aleksandra Osztynowicz
Key takeaways
- Multimodal models process text, images and often audio in one model and answer questions about what they see.
- Typical uses are document processing, checking photos, reading displays and verifying packaging or assembly.
- The big advantage: requirements can be described in words, and prototypes emerge without thousands of labelled examples.
- Production needs testing on your own data. In industrial inspection, specialised methods are often still more accurate.
What multimodal models are
Classic neural networks specialise in one type of data, such as images or text. Multimodal models combine several data types in one system: they look at a photo, read an instruction with it and answer in text. That makes tasks possible that used to need several separate models, such as describing an image, answering questions about it or understanding text in a document in context.
For companies, one thing above all is new: requirements can be described. Instead of labelling thousands of examples of “correctly assembled”, you explain to the model what to look for.
Applications and effort
| Application | What the model takes over | Effort |
|---|---|---|
| Documents | reading invoices, delivery notes, forms and attachments and passing on data in structured form | medium: variety of formats, checks against master data |
| Damage checks | checking photos of parcels, vehicles or goods for visible damage and documenting it | low to medium: clear criteria, example images |
| Reading displays | reading meter values, displays or labels from photos | medium: error rate must be measured on real photos |
| Packaging and assembly | checking whether all parts are present and correctly placed, and giving guidance | medium: step-by-step instructions, tests per variant |
| Industrial inspection | detecting fine defects on surfaces or components | high: often only alongside specialised models |
In practice: Radaway
At the bathroom equipment manufacturer, orders arrive by email, often with the order in an attachment. After our improvements, the system also processes orders in attachments: coverage there went from 0 to 100%, and manual intervention fell by 90% overall.
Example: reading meter values from photos
In a 2024 test, a camera photographed a water meter several times a day. A red rectangle marked the counter, and the model was to return the value in a fixed format so it could be processed directly.
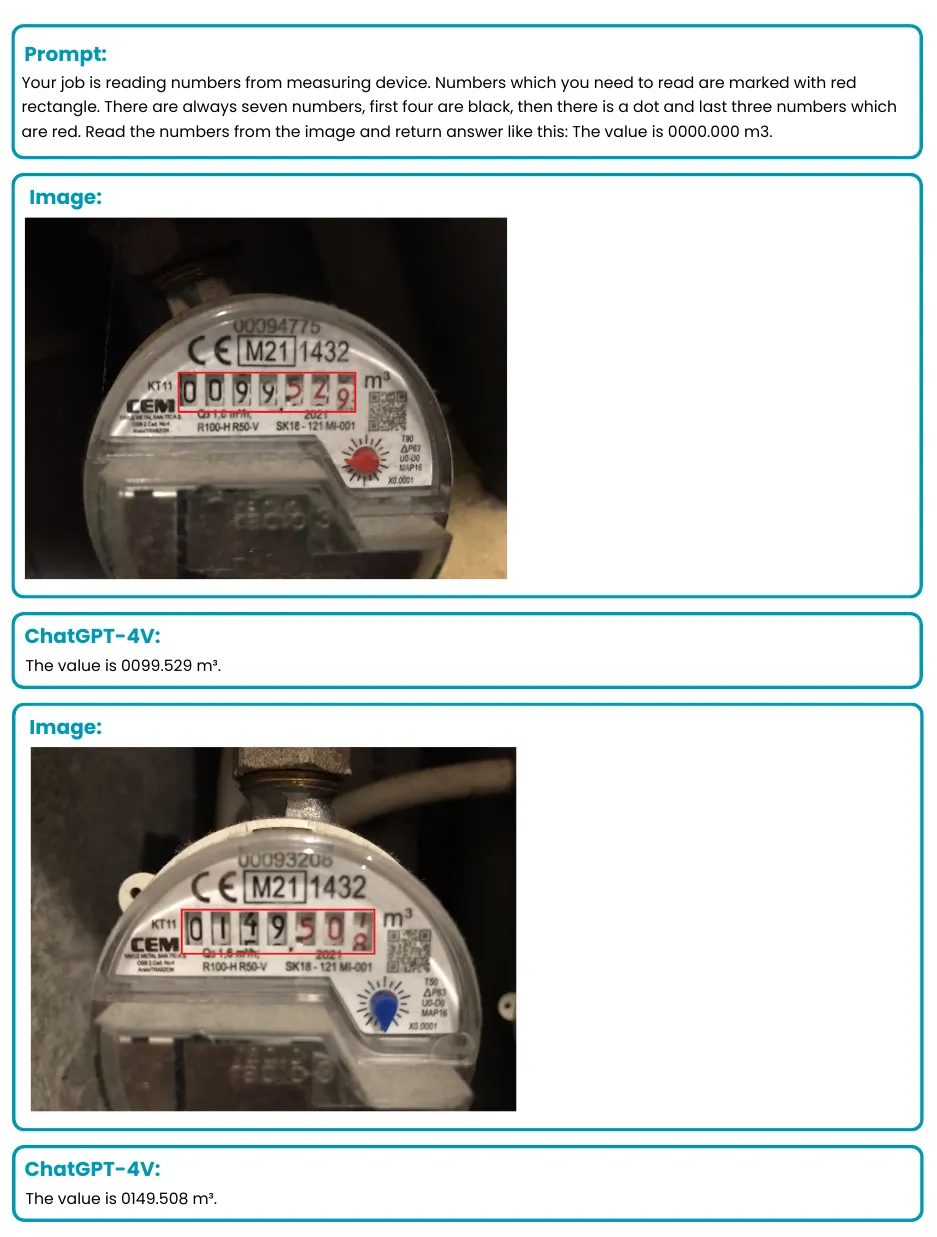
The example shows what matters: a clear instruction, a fixed output format and a prepared image, here the marked area.
What makes a good instruction
- Clear and step by step: describe exactly what the model should do with the image, in the right order.
- Give context: what it is about, which variants occur, which errors are typical.
- Fixed format: specify an answer structure when the result is processed further.
- Show examples: for fine differences, include one or more example images.
- Allow uncertainty: let the model answer “not readable” instead of guessing.
Where the limits are
Our 2024 tests showed three typical weaknesses. Models have improved since, but these points should still be checked in every project:
- Counting: reliably counting many similar objects often only worked with very specific instructions.
- Exact positions: models tend to say “bottom left” rather than give exact coordinates. Precise location needs classic computer vision.
- Text recognition: individual characters were added or left out. Where every digit counts, plausibility checks are needed.
In industrial defect detection, specialised methods are often still more accurate. Our test on this concludes: a complement, not yet a replacement. More in the article LLMs in visual inspection and quality control.
How to proceed
- Define task and criteria: what should be recognised in the image or document, and what counts as correct?
- Prototype with a multimodal model: show within a few days whether the task can be solved at all.
- Measure on real data: determine the error rate on a representative sample of your own images or documents.
- Decide: multimodal model, specialised model or a combination.
- Integrate and monitor: pass results to existing systems and check them continuously in production.
How models are compared systematically is covered in our article LLMOps for enterprises: benchmarking and comparing vision LLMs.

Evaluating images and documents automatically?
We test on your own data whether a multimodal model solves your task reliably and plan the path into production.
Request a process analysisFrequently asked questions
AI models that process several data types such as text, images and often audio together. They can, for example, evaluate a photo along with an instruction and answer in text.
For example processing invoices, delivery notes and attachments, checking photos for damage, reading meters and displays, and verifying packaging or assembly.
Usually not to get started. Requirements can be described in words and with a few example images. For production, quality should be measured on a representative sample of your own data.
At theBlue.ai the analysis is available at a fixed price from €3k. Implementation typically runs between €25k and €100k, with a scoped estimate at the end of the analysis.
Aleksandra has been building custom AI solutions at theBlue.ai since 2021, with a focus on agentic implementations and local LLM deployments that precisely fit enterprise needs. As an AI Engineer, she helps organizations automate their processes with production-grade systems, from on-premise open-source models to RAG-based internal knowledge bases for regulated industries, and continuously expands her knowledge in the rapidly changing world of artificial intelligence.
In her articles, she shares practical experience from real enterprise AI projects and shows that deploying AI in companies doesn’t need to be complicated.