Computer Vision · Segmentation
Zero-Shot Image Segmentation: Recognising Objects Without Large Datasets
Classic image segmentation needs thousands of hand-labelled examples per object class. Zero-shot models also segment objects they never saw in training. For MedTech and quality inspection, that mainly means faster training data and faster prototypes.
 Aleksandra Osztynowicz
Key takeaways
- Semantic segmentation assigns a class to every pixel of an image. Precisely labelling the training data is the biggest effort.
- Zero-shot models such as the Segment Anything Model (SAM) can cut out any object, even without training on that exact class.
- Grounded SAM combines text-based object detection with SAM. Since November 2025, Meta’s SAM 3 segments directly from short text descriptions.
- In MedTech and quality inspection, such models mainly speed up annotation. Specialised images need validation and often adaptation.
Why segmentation takes so much groundwork
Semantic segmentation assigns a class to every pixel of an image, such as bone, vessel, scratch or background. That gives a more precise picture than a box around the object and is the basis for measurement, 3D models or surface inspection.
The catch lies in the training data. For every class, a classic model needs many images in which someone has traced the outlines pixel by pixel. At apoQlar, radiologists and technicians traced anatomical structures by hand for hours per patient before we could train our own models for automatic segmentation.
What zero-shot learning means
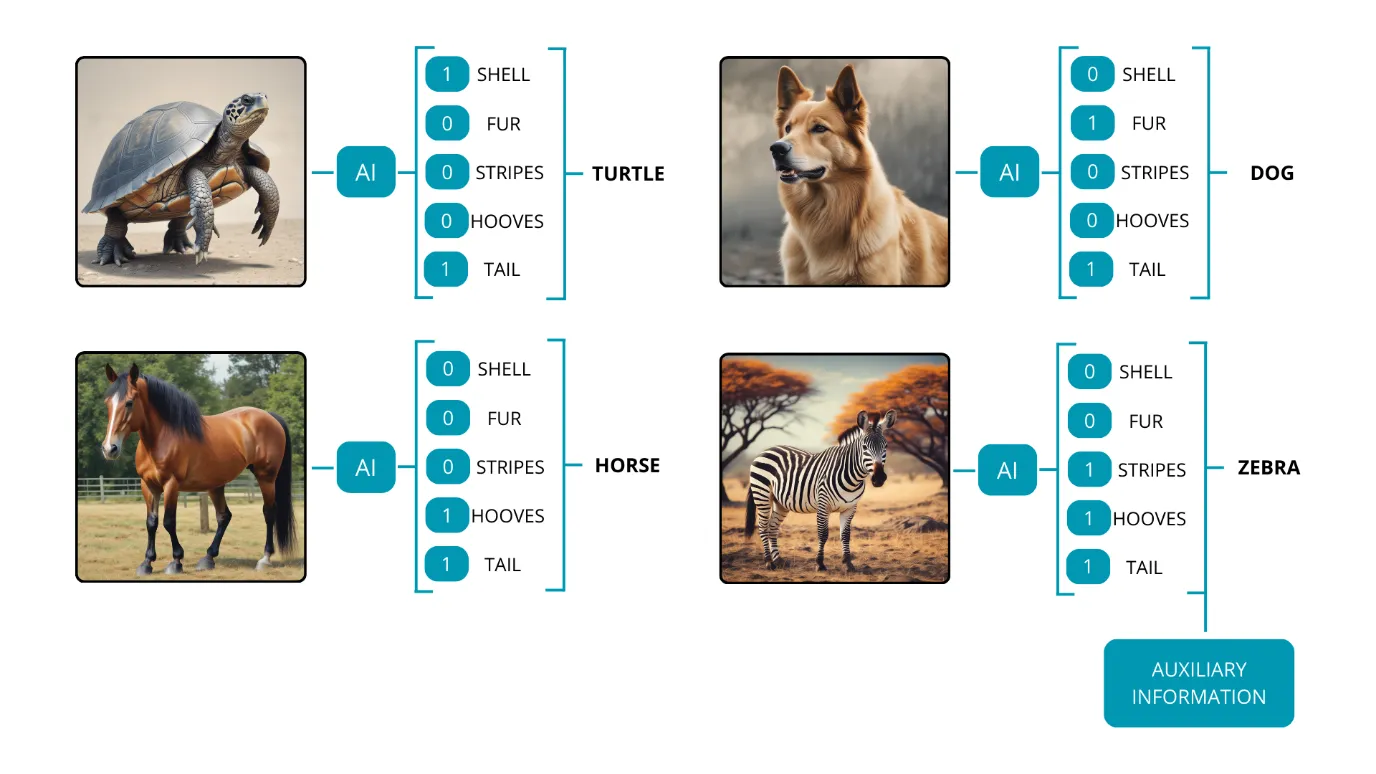
In zero-shot learning, a model recognises classes that did not appear in training. It learns general features and uses additional information, such as a description. A model that knows turtles, dogs and horses can classify a zebra once it learns: a horse with black and white stripes.
Segment Anything and Grounded SAM
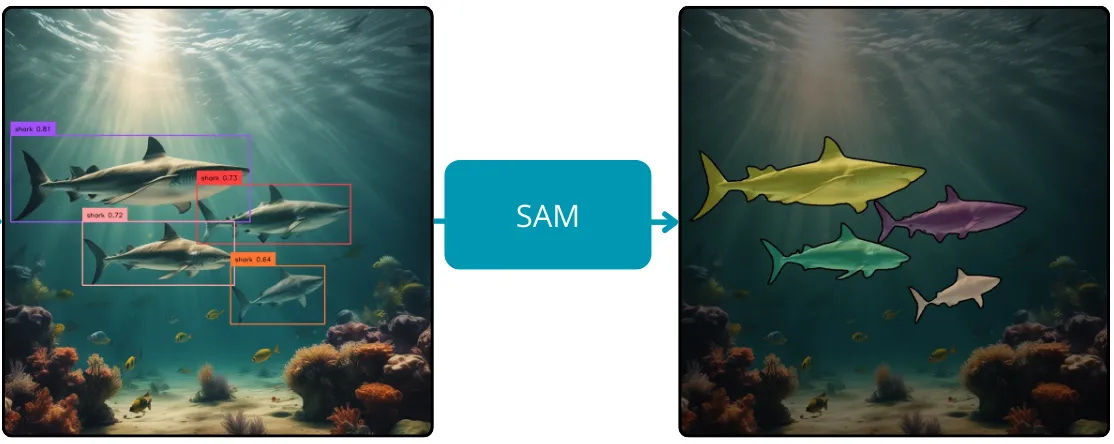
For segmentation, Meta put this idea into practice with the Segment Anything Model (SAM): the model learns to separate any object from its background rather than specific classes. It was trained on more than one billion segmentation masks. SAM creates masks for the whole image or for a specific object marked with a box or point.
SAM does not know what it is cutting out, though. Grounded SAM adds that: the detection model Grounding DINO finds objects from a text such as “shark”, and SAM creates the precise mask for every box found.
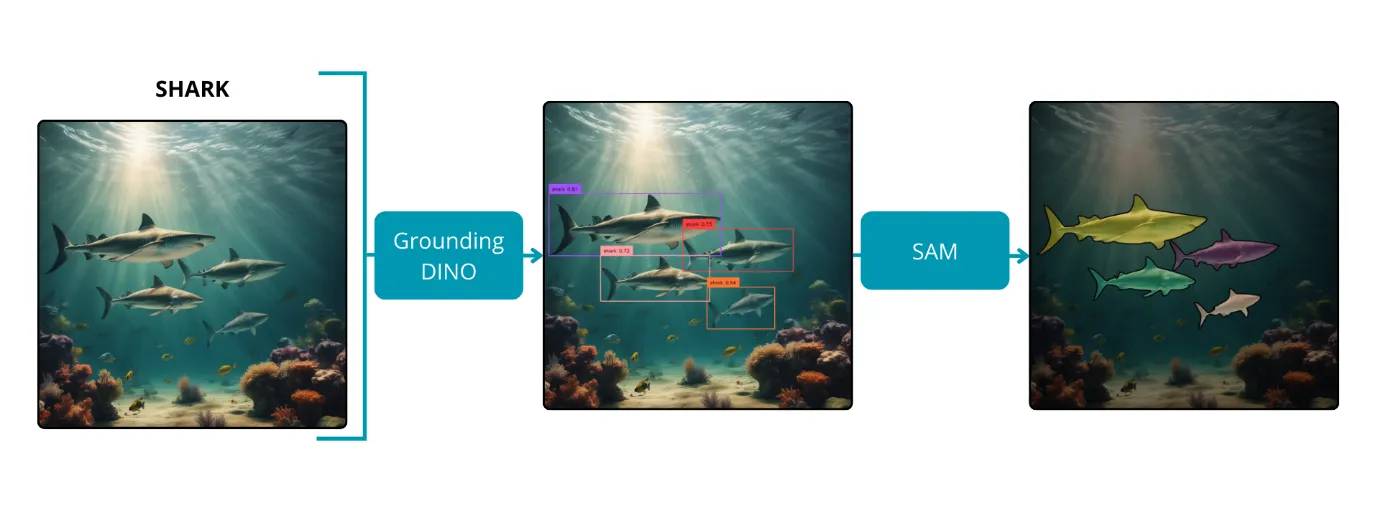
Development has moved on. SAM 3, released by Meta in November 2025, takes short text descriptions or example images directly, segments all matching objects and also tracks them in video.
Source: Meta AI, SAM 3
What this means for MedTech and quality inspection
| Use | What zero-shot segmentation contributes |
|---|---|
| Annotation | masks are proposed and experts only review and correct them instead of drawing by hand |
| Prototypes | first results on your own images before training a dedicated model |
| Quality inspection | selecting and measuring parts, surfaces or packaging by text description |
| Rare cases | covering new object or defect types without a large new dataset |
| MedTech | pre-segmenting structures as a starting point for expert refinement |
The biggest lever is usually annotation: when masks are proposed and only reviewed, training data for specialised models comes together much faster.
Where the limits are
- Specialised images: general models learn mostly from everyday photos. MRI, CT, microscopy or X-ray images look different and need careful validation and often adaptation.
- Fine details: small scratches, fine vessels or blurred boundaries are not always captured reliably.
- Technical terms: text descriptions work well for everyday words and less well for specialist vocabulary.
- Responsibility: in medicine and safety-relevant inspection, assessment and sign-off stay with experts.
In practice the best solution often combines both: zero-shot models speed up annotation and prototyping, and specialised models deliver the accuracy needed in production. How well multimodal models perform in quality inspection is shown in our article LLMs in visual inspection and quality control.
In practice: apoQlar
For surgical planning with VSI HoloMedicine®, we developed U-Net models, one variant per anatomical structure, for MRI and CT. Segmentation that took hours per patient by hand now takes seconds.
Segmentation for your image data?
We look at whether zero-shot models are enough for your images, how they speed up annotation and when a dedicated model pays off.
Request a process analysisFrequently asked questions
An approach in which a model recognises classes that did not appear in its training. It uses general features and additional information such as a text description.
A segmentation model from Meta that has learned to separate any object from its background. It was trained on more than one billion masks. SAM 3 from November 2025 also segments from short text descriptions and in video.
Mainly faster annotation of training data, prototypes on your own images and rare object or defect types in quality inspection.
Usually not as is. General models learn mostly from everyday photos. MRI, CT or microscopy need careful validation, often adaptation or specialised models, and assessment stays with experts.
Aleksandra has been building custom AI solutions at theBlue.ai since 2021, with a focus on agentic implementations and local LLM deployments that precisely fit enterprise needs. As an AI Engineer, she helps organizations automate their processes with production-grade systems, from on-premise open-source models to RAG-based internal knowledge bases for regulated industries, and continuously expands her knowledge in the rapidly changing world of artificial intelligence.
In her articles, she shares practical experience from real enterprise AI projects and shows that deploying AI in companies doesn’t need to be complicated.